TL;DR

Get office and shipping supplies delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
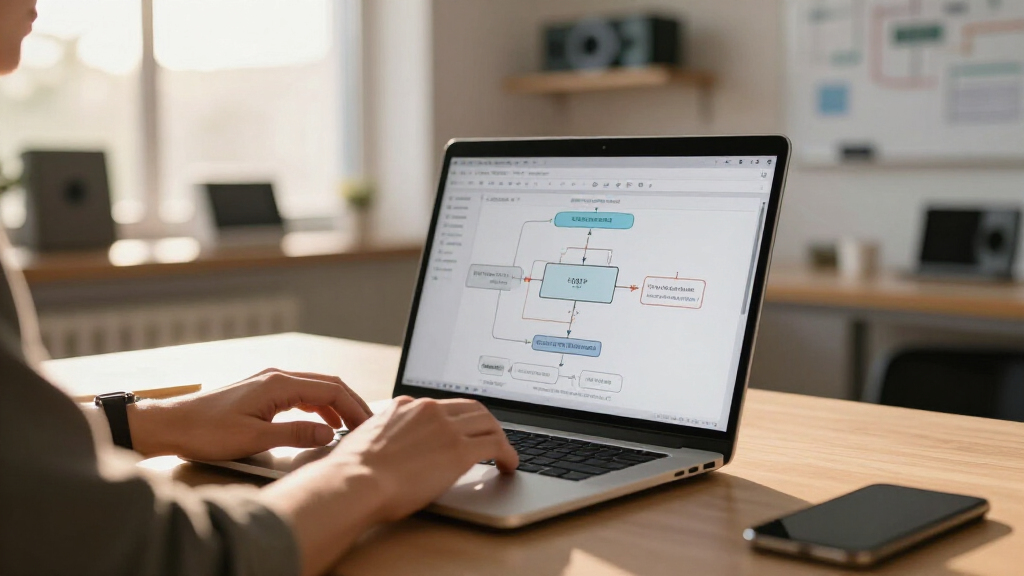
This article outlines a step-by-step approach to building a local AI document pipeline, focusing on architecture, modular components, and operational principles. It emphasizes maintaining control, flexibility, and data provenance for reliable, scalable AI workflows.
Why a Modular, Local Pipeline Matters for AI
Building a local document pipeline with clear architecture principles enhances control, data security, and flexibility. It allows organizations to adapt models quickly, ensure compliance with data governance, and maintain operational resilience. This approach reduces dependencies on external services, mitigates risks associated with model updates, and provides detailed provenance for auditability, making it especially relevant for regulated industries and organizations prioritizing data sovereignty.wireless document scanner for AI OCR
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Emerging Industry Practices and Proven Architectures
Recent developments in AI document processing emphasize modularity, control, and transparency. Demonstrations from companies like Hugging Face have shown the feasibility of running capable models on local infrastructure. The industry is shifting from monolithic pipelines to component-based architectures, with a focus on simple, maintainable, and replaceable modules. The approach aligns with recent regulatory changes, such as the AI Act’s transparency rules, which encourage local inference and data governance. These trends are supported by practical implementations that prioritize minimal dependencies, content-based idempotency, and detailed provenance tracking, providing a foundation for scalable, compliant AI workflows.“The pipeline should be a series of narrow, single-purpose components that can be replaced or upgraded without disrupting the entire system.”
— Thorsten Meyer
Remaining Questions About Implementation and Scalability
It is not yet clear how well this architecture scales with very large document volumes or complex workflows. While the design principles are sound, real-world performance, maintenance overhead, and integration with existing enterprise systems require further testing and validation. Additionally, model swapping and schema evolution pose ongoing challenges that need careful management.Next Steps for Deploying and Evolving Local Document Pipelines
Organizations should begin prototyping this architecture in controlled environments, testing component replacements, and refining provenance tracking. Future developments may include automation of schema updates, enhanced monitoring, and integration with enterprise data governance tools. Industry groups are expected to share best practices and tooling to support broader adoption of these principles in production settings.Key Questions
Why focus on local infrastructure for AI document pipelines?
Local infrastructure offers greater control over data, compliance with regulations, and reduced dependency on external providers, which is critical for sensitive or regulated industries.
How does content hashing improve pipeline reliability?
Content hashes enable idempotent processing, safe retries, and prevent duplicate work, ensuring data consistency and simplifying error recovery.
Can this architecture adapt to different types of documents?
Yes, the modular design allows customization of ingestion, OCR, and extraction components for various document formats and use cases.
What are the main challenges in implementing this pipeline?
Challenges include managing schema evolution, ensuring model interchangeability, and scaling processing for large volumes, which require careful planning and testing.
Source: ThorstenMeyerAI.com
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.