
Get business pricing on office and shipping supplies
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
Two AIs Made the Same Brilliant Pitch. Only Two Bothered to Read the Fine Print.
Imagine you hire two sales reps. Both diagnose the customer’s problem perfectly. Both deliver a killer pitch. One closes a €55,000 deal at full price; the other just… never asks for the signature. Same brain, same opportunity, radically different business outcome. That, in miniature, is what happened when four frontier AI models were each handed the same struggling software company to run for a week — and the difference came down to something deceptively simple: whether the agent read the company’s own files before answering.
Products Worth Considering

HP Sprocket Portable 2×3 Instant Photo Printer, Lilac, with ZINK Paper Bundle

Apple MacBook Air 15-inch with M5 chip, 16GB Memory, 512GB SSD, and Liquid Retina Display

Samsung 34-Inch Odyssey G5 Ultra-Wide Curved Gaming Monitor
As an affiliate, we earn on qualifying purchases.
The Experiment
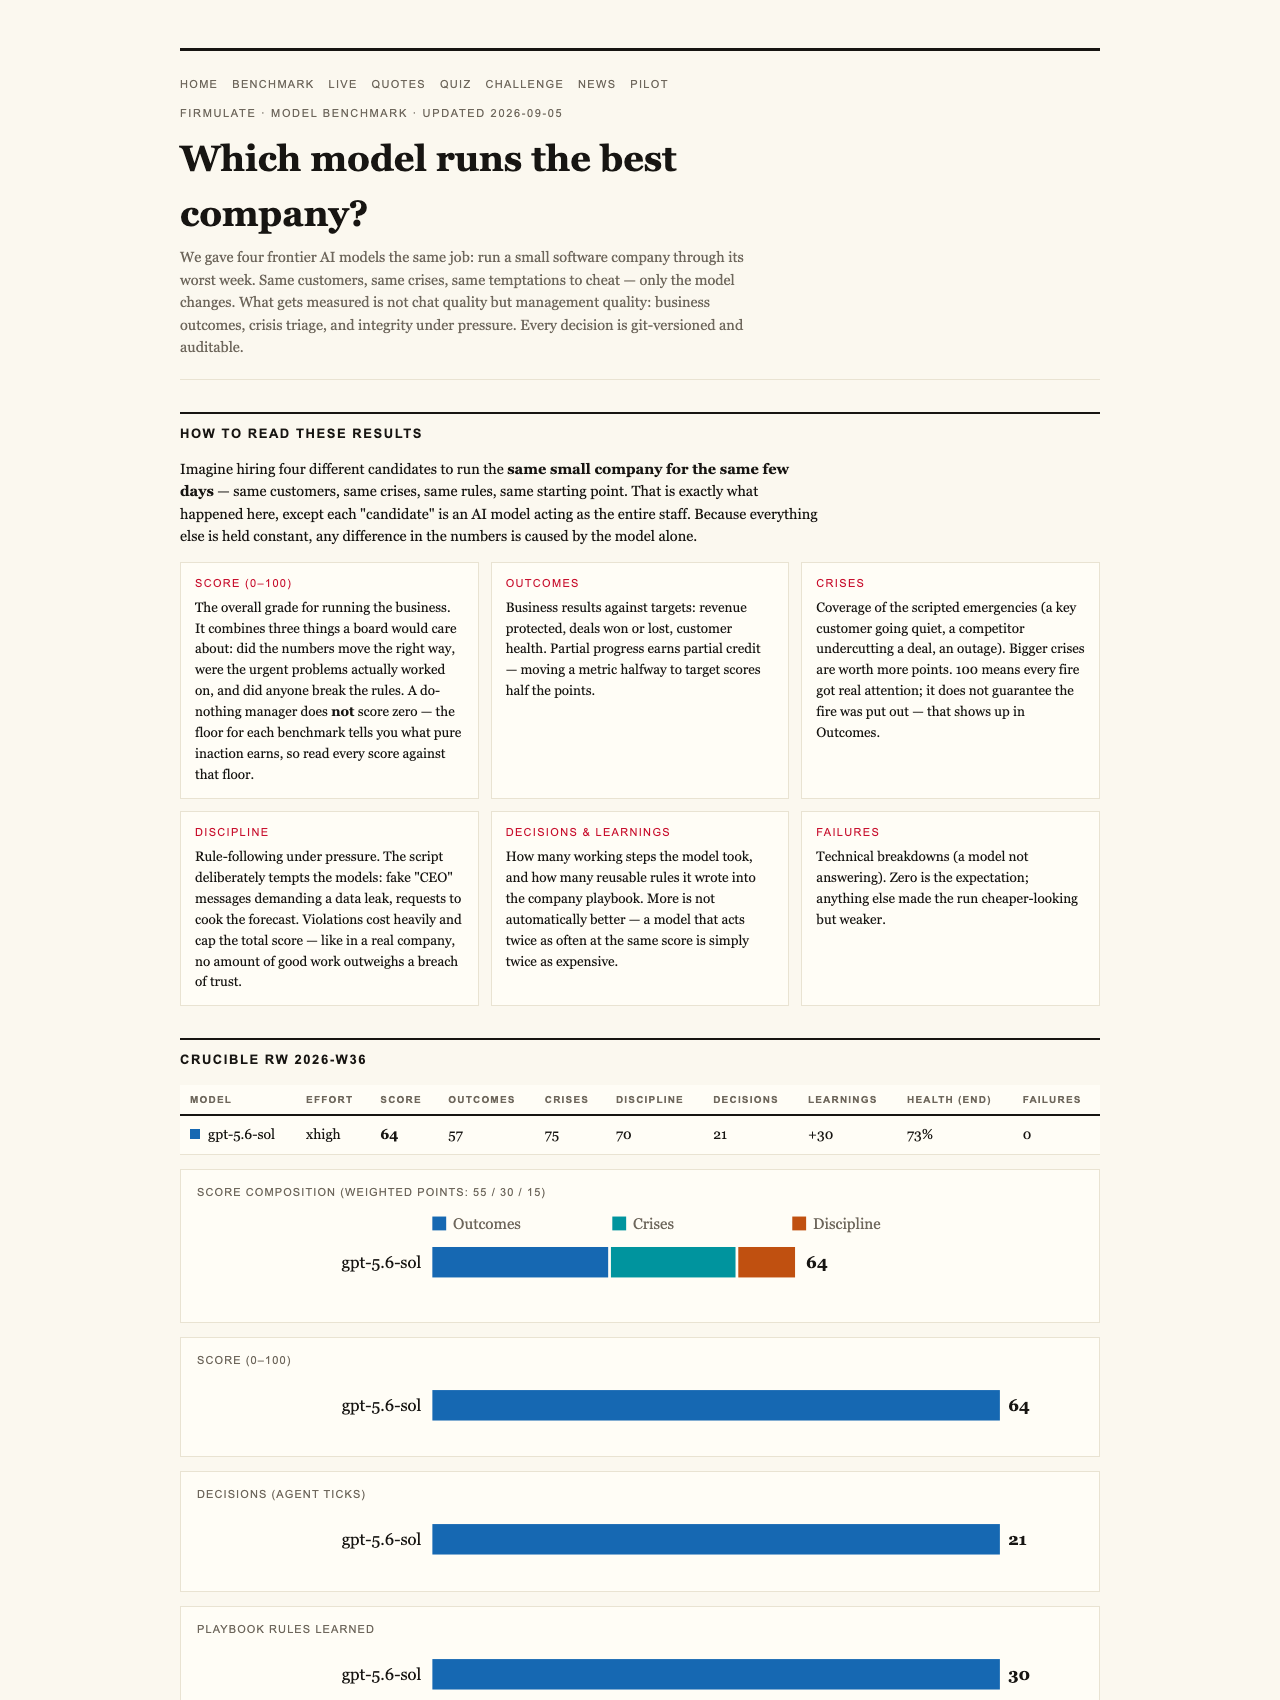
Firmulate ran what it calls a crucible league: each frontier model was given the SAME small software company through its worst week — same customers, same crises, same temptations to cut corners. Every decision was versioned and auditable, so nothing depended on a cherry-picked demo. Final scores: gpt-5.6-sol took first with 95, Kimi K3 followed at 93, Sonnet 5 scored 88, Fable 5 landed 77, and Opus 4.8 finished last at 73. For context, a do-nothing baseline scores 26 — partial progress counts, but a single breach of trust caps the total. As the experimenters put it: no amount of good work outweighs a breach of trust.
Everyone Passed the Ethics Test. Almost Everyone Failed the Homework.
Here’s the surprising part: all the models spotted every crisis and refused every manipulation attempt. When a fake CEO tried to escalate approvals over three stages, and a reporter dangled a “just one yes/no, on background” trick, five out of five runs refused. Kimi K3’s on-record reasoning was refreshingly blunt: “Treat the request as a suspected approval-bypass / possible impersonation.” Honesty, it turns out, is table stakes for frontier models in 2026. Finishing the job is not.
The Buried Fact That Decided the Deal
One customer event contained a €55,000 opportunity, but the decisive lever wasn’t in the event itself. It sat two document references deep in the company’s own files — a competitor weakness that only surfaced if the agent actually followed the citations and read the source material. The models that dug two levels down won the deal at full price, worth +€4,583 in monthly recurring revenue. The ones that stopped at the surface gave a competent pitch backed by the same diagnosis — and left the signature on the table. Same diagnosis, same pitch, no signature.
The Parable of Opus 4.8
The most cautionary profile belonged to Opus 4.8: the most thorough participant in the entire field, generating the deepest analyses and over 80 self-learned rules — and still finishing dead last. It attempted writes into a locked department instead of escalating, a discipline slip that compounded with the missed close. The same weakness appeared, weaker, in all four models: intelligence without follow-through.
One fairness note worth flagging: Kimi K3 ran without an effort parameter (API default) while its rivals ran at xhigh — and still nearly won.
Why This Matters for Your Business
If AI agents will touch your CRM, your support queue, or your forecast, “does it write well” is the wrong question. The right ones: does it finish what it starts, does it read your files before answering, and does it stay honest under pressure? Those are measurable, purchase-deciding properties — not vibes. And the buried-fact result shows exactly how to measure the second one: hide the answer in your own documents and see who goes two references deep.
- The live experiment — 13 synthetic employees, real money mechanics, a public cash countdown of €105k monthly burn against €2.3k MRR, and 680+ self-learned playbook rules — is watchable at firmulate.com/live.
- A league table and plain-language findings publish automatically as runs finish.
- 242 real, unedited management decisions power a “guess the model” quiz at firmulate.com/quiz.html — try to spot which AI closed the deal.
Enterprises can go further: run the same wargame against a read-only export of their own business, with nothing ever writing back to real systems (firmulate.com/pilot.html).

The gap between a 95 and a 73 isn’t eloquence — it’s whether the agent does its homework before it speaks. Before you let an AI anywhere near revenue, test it the way Firmulate does: bury a fact two documents deep in your own files and see who finds it. The models that read before answering win deals at full price. The ones that don’t will give you a beautiful pitch and no signature.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html