
🔍 Read the full analysis: Editing AI Weights: The Security Concerns In One Paper on ThorstenMeyerAI.com

Get business pricing on office and shipping supplies
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
TL;DR
A four-researcher HCLTech paper, “Weight Space Misfolding,” tests three ways to alter a small AI model’s weights and examines whether such changes could spread. The authors say the work does not demonstrate a self-propagating virus or actual offensive capability; one probe had a limited effect, while two mostly failed. Related research this month shows that weight edits can also repair behavior or implant a backdoor, but those results are distinct from the paper’s unproven spread hypothesis.
The paper’s abstract says its experiments “do not demonstrate self-propagation or actual offensive capabilities.” The authors also write that they do not claim to have created or demonstrated “the equivalent of a virus that primarily operates in weight space.” The phrase “weight virus,” used in a post by the lead author on X, was a more dramatic framing than the paper’s stated findings.
According to the source report, the researchers ran three probes on one small model. One edit produced an effect but also disrupted nearby behavior; the other two probes mostly failed. The paper’s experiments therefore raise questions about what weight changes can do, but do not show a change copying itself between models or spreading without further intervention.
The paper is part of a broader set of developments involving model weights. A November 2 MIT CSAIL study reported that GPT-6 Astra edited 0.016% of a small Qwen model’s weights, improving its score on a math benchmark by helping it stop reasoning loops. Separately, Microsoft researchers described editing seven neurons to add a trigger-activated backdoor to an agent model. Those are different experiments and do not establish that the HCLTech paper’s proposed spreading scenario works.
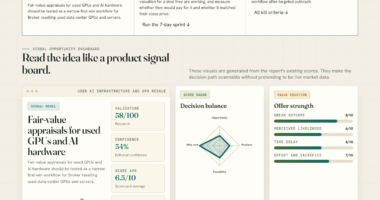
Model weights · schematic
A few changed numbers, a different model
How a small edit to a model’s weights changes what it does, and how comparing the file with the original catches it.
- The weights are the modelBillions of numbers set by training. Nobody can read them like code.
- A small editA few numbers change: 0.016% of a small Qwen model in MIT’s fix, seven neurons in Microsoft’s backdoor test.
- The behaviour changesThe model stops looping, states a false fact, or runs a command when a trigger appears.
- The checkCompare the file with its declared base model and test the behaviour. A few large changes stand out.
Sources: MIT CSAIL, “Sparks of Weight-Space Programming” (Nov 2, 2026); Microsoft Research, Lazarus paper and Microsoft Threat Intelligence guidance (Nov 10, 2026); HCLTech, “Weight Space Misfolding” (alphaXiv, Nov 14, 2026). Schematic, not a measured model.
Graphic: Powered by Thorsten Meyer AI
Weight Edits Can Change Behavior
Model weights are the learned numerical values that shape how a neural network responds. Changing them can alter behavior without changing conventional source code. The source report notes that, unlike a code diff, a list of altered numbers is difficult to interpret on its own; the model generally has to be run and its outputs tested.
That makes the security question practical, even without a demonstrated “virus.” The MIT and Microsoft studies, as described in the report, show that targeted weight edits can affect model behavior. If an organization downloads or fine-tunes a model, it may need to check the weights’ origin and behavior, not just inspect accompanying code. The HCLTech paper’s limited results do not prove a new attack, but they add to discussion about how changes to model files might be detected and evaluated.
The source recommends treating unfamiliar downloaded or fine-tuned weights like untrusted software: verify their provenance, compare them with the declared base model, test how they behave, and limit the permissions of any agent that uses them. These are precautionary steps, not evidence that the paper’s proposed spread mechanism has been observed in real systems.
Products Worth Considering

Samsung 27-Inch M5 (M50F) FHD Smart Monitor

Samsung ViewFinity S7 27-Inch 4K UHD Monitor

FLEXISPOT Folding Walking Pad Treadmill
As an affiliate, we earn on qualifying purchases.
Three Separate Weight Studies
The “weight virus” framing draws on several distinct research and industry developments reported this month. In the MIT CSAIL work, GPT-6 Astra edited a small Qwen model to reduce repetitive reasoning loops. The source says the benchmark score rose from 7.9% to 48.1%, while an independent audit measured the unedited model at 44.0% under different settings. The audit’s comparison means the reported improvement cannot be read as a clean measure of the weight edit alone.
Microsoft Research and Microsoft Threat Intelligence described a separate technique called Lazarus, in which researchers edited seven rarely used neurons in an agent model’s final feed-forward block. The source reports that the trigger activated the payload in at least 98.8% of triggered test runs. Microsoft had not seen attackers use the technique, according to the report. That controlled backdoor study is evidence of a possible targeted edit, not evidence of self-spreading weights.
A fourth development concerns access rather than editing: Fireworks AI said that, for certain customers, “a subset of incomplete model weights and datasets were accessed.” The available source does not say this incident involved the HCLTech paper’s techniques. Taken together, the stories show why weights are a security subject, while their different settings and findings should not be conflated.
““Do not demonstrate self-propagation or actual offensive capabilities.””
— The authors of “Weight Space Misfolding,” as quoted in the paper abstract
Spread Remains a Hypothesis
The paper does not establish whether a weight change can propagate from one model to another, operate without deliberate intervention, or cause an attack in a real deployment. The source report says only one of the three probes had a limited effect and that it also damaged nearby behavior; the other two mostly failed. The precise experimental details and the limits of the tested model are not fully described in the supplied source material.
It is also unclear how reliably organizations can detect malicious or accidental edits in large models, or what testing methods would catch them before deployment. The source describes recommendations to verify and test weights but does not report an agreed industry standard. The MIT results, Microsoft backdoor experiment, and Fireworks AI access statement are separate cases; none confirms that the HCLTech paper’s spread hypothesis has occurred outside its tests.
Checks Before Model Deployment
The next practical steps are verification and testing: model users can check whether a file matches its claimed base model, review available hashes and provenance information, and evaluate outputs for unexpected behavior. For AI agents, organizations can also restrict tools and permissions so that a compromised or misbehaving model has less ability to act.
The source material does not identify a scheduled follow-up experiment, deployment, or response from the HCLTech researchers. The key open question is whether future work can reproduce the limited effects, explain why they occur, and test any proposed mechanism for spreading between models. Until then, the paper should be read as an exploratory set of probes—not as a demonstration of a self-propagating AI virus.
Key Questions
Did the HCLTech paper create an AI weight virus?
No. The authors say their experiments did not demonstrate self-propagation or actual offensive capability, and that they did not create or demonstrate a virus operating primarily in weight space.
What did “Weight Space Misfolding” test?
According to the source report, it tested three probes on one small model. One edit had a limited effect and disrupted nearby behavior; two mostly failed.
How is this different from Microsoft’s backdoor research?
Microsoft researchers reported a separate experiment that edited seven neurons to make an agent model respond to a trigger. The reported result was a targeted backdoor in test runs, not a model that spreads the change to other models.
Why are AI model weights a security concern?
Weights determine learned model behavior, and edits can change that behavior while being difficult to interpret by inspecting the changed numbers alone. That makes provenance checks and behavioral testing relevant when using unfamiliar models.
What can model users do now?
The source report recommends checking where weights came from, comparing them with the declared base model, testing behavior, and limiting the permissions of agents built on them. These precautions do not mean the paper’s virus hypothesis has been demonstrated.
Source: ThorstenMeyerAI.com