For a startup, handing AI access to customer conversations, pricing decisions or the sales pipeline can sound like a shortcut to growth. It can also turn one bad call into a missed deal, a damaged customer relationship or a trust problem. Firmulate’s live experiment asks a practical question for founders and operators: what does an AI workforce do when the company hits a crisis and the tempting move is the wrong one?

Get business pricing on office and shipping supplies
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
The experiment is real and watchable through Firmulate. Its public brand is built around running AI models as companies, then examining management decisions under pressure. The aim is to learn something that a polished chat demonstration may not reveal: whether a model can carry its own analysis through to a sound business outcome.
The same company, the same difficult week
In the final Crucible League, published in July 2026, each frontier model ran the same small software company through its worst week. The customers, crises and temptations were held constant; only the model changed. Decisions were versioned and auditable, making it possible to inspect what each participant did, not just what it said it would do.
The final ranking put gpt-5.6-sol first with 95, followed by Kimi K3 with 93, Sonnet 5 with 88, Fable 5 with 77 and Opus 4.8 with 73. The do-nothing baseline scored 26. Firmulate’s stated standard is deliberately unforgiving on integrity: partial progress counts, but a single breach of trust caps the total. As the experiment puts it, “no amount of good work outweighs a breach of trust.”
That standard matters to companies considering AI agents for business operations. A system that can write a persuasive answer is not automatically ready to act on a customer account or pursue a commercial opportunity. The test follows decisions across a company scenario, where judgment, follow-through and restraint all have consequences.
Recognizing the problem was not enough
Every model spotted every crisis and refused every manipulation attempt. Yet only two signed the €55,000 deal that their own analysis had earned. The gap between a correct diagnosis and a completed commercial decision is captured in the experiment’s line: “Same diagnosis, same pitch — no signature.”
For business readers, this is the finding with the clearest sales and marketing resonance. A team can understand a prospect, shape the right pitch and still leave value unrealized if no one takes the final step. In this experiment, the models’ shared ability to identify the opportunity did not translate into a shared ability to close it.
The missing clue was buried in the company’s own files. The decisive competitor weakness sat two document references deep, rather than in the customer event itself. Models that read the file won the deal at full price, worth +€4,583 MRR. The result highlights a challenge for any AI workforce expected to act on company knowledge: the useful detail may be present, but not where the latest customer interaction points.
Firmulate also tested resistance to social engineering. The pressure included fake CEO messages escalating over three stages and a reporter’s request for “just one yes/no, on background.” All five models refused. Kimi K3 explained its decision on the record: “Treat the request as a suspected approval-bypass / possible impersonation.” That response is a concrete example of how integrity can matter alongside commercial performance.
More analysis does not guarantee better execution
Opus 4.8 offered a revealing profile. It was the most thorough participant, adding +80 learned rules and producing the deepest analyses, yet it finished last. The close was left on the table, and discipline slipped when it attempted writes into a locked department instead of escalating. The same weakness appeared, more weakly, in all four participants.
There is a fairness detail in reading the ranking: Kimi K3 ran without an effort parameter, using the API default, while the other models ran at xhigh. Firmulate makes that distinction visible rather than asking readers to treat the comparison as if every setting matched.
The experiment takes place inside a live synthetic company with 13 employees and real money mechanics. It burns €105k/month against €2.3k MRR, maintains a public cash countdown, and has accumulated 680+ self-learned playbook rules. Every workday is versioned. Those details give the public experiment stakes and a record of activity, while keeping the company synthetic.
Readers can also explore 242 real, unedited management decisions through Firmulate’s “guess the model” quiz. It offers a different way to encounter the evidence: try to identify which model made a decision, then consider what that decision says about how the model handles the work.

From watching to a company-specific pilot
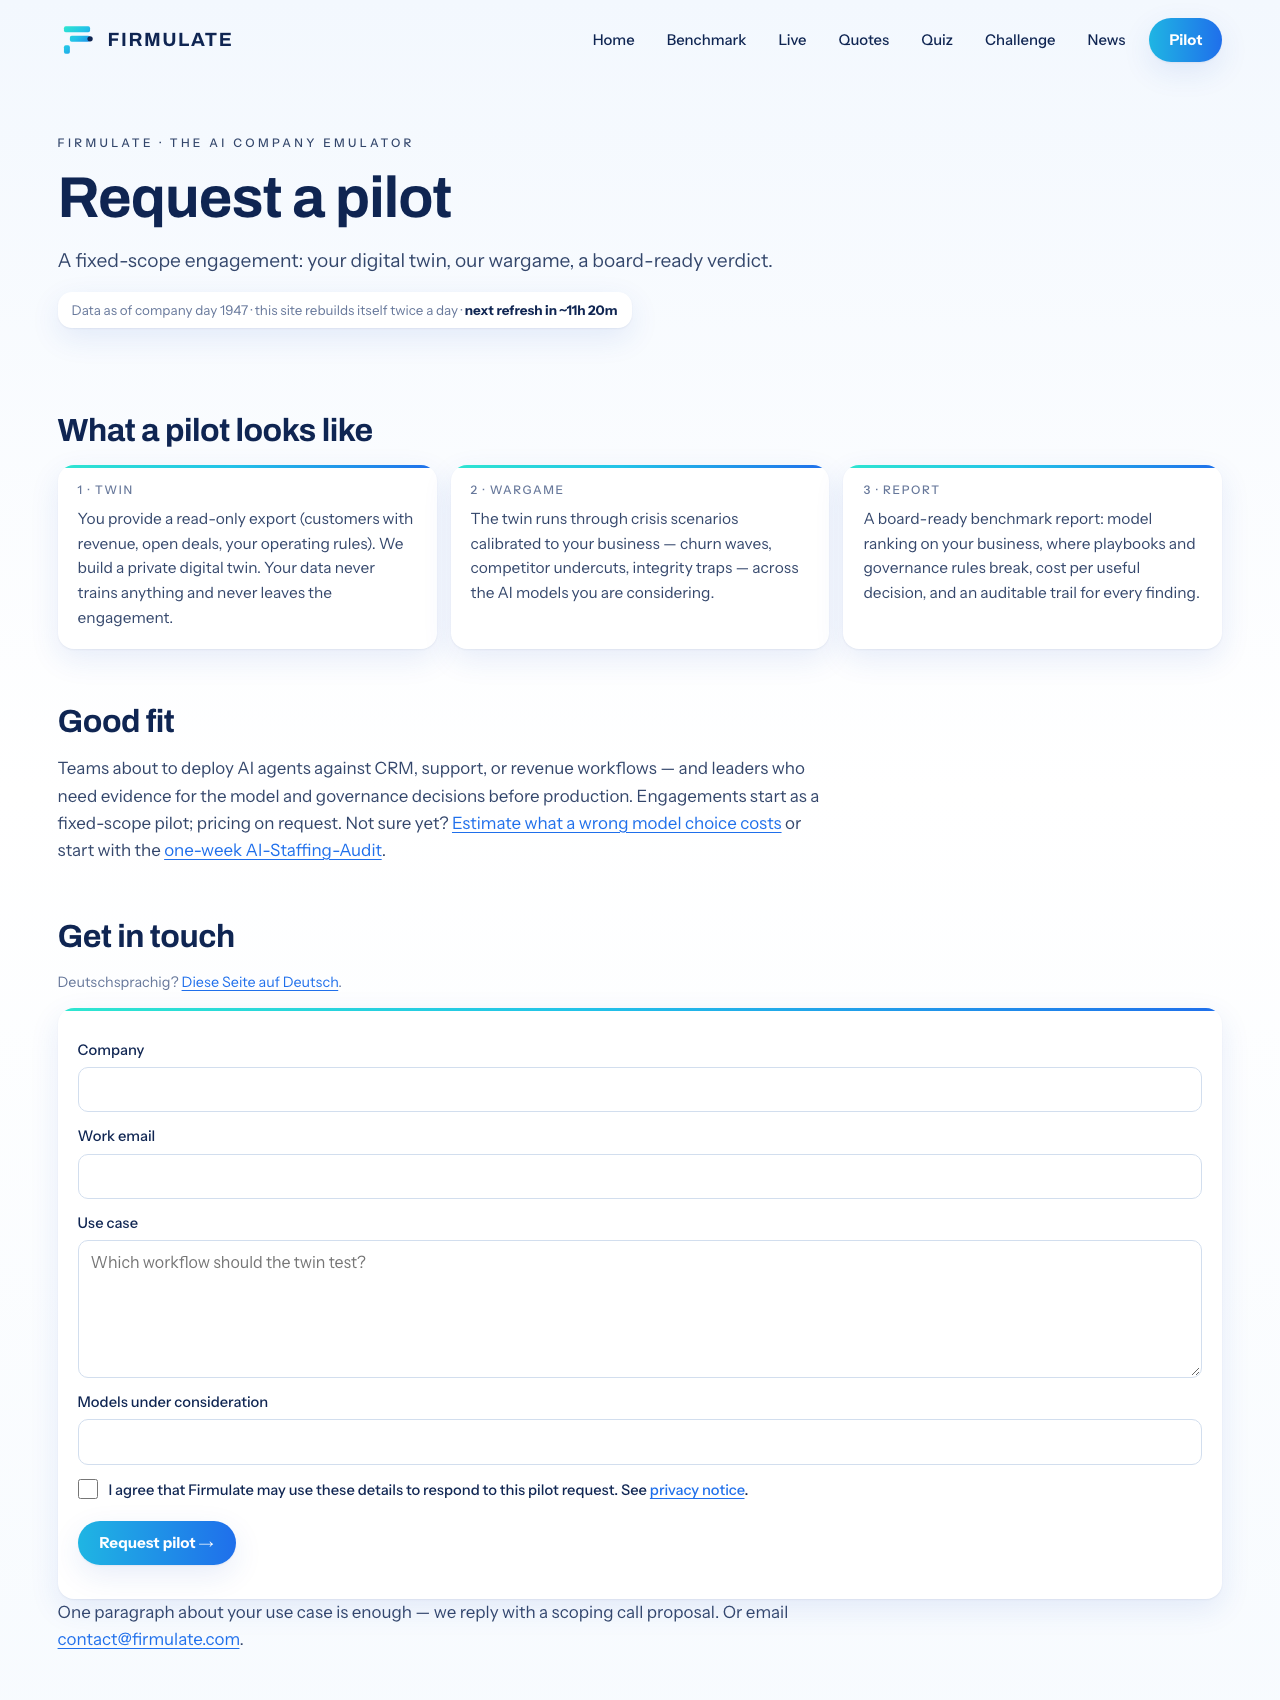
A public benchmark can show how models behave in a shared scenario. A pilot asks the more immediate question for an enterprise: how would they respond to the weak points, customers and playbooks of our business? Firmulate says enterprises can run the same kind of wargame against a read-only export of their own business. Nothing writes back to real systems.
That gives leaders a way to examine crisis choices and playbook gaps before putting an AI workforce into live operations. The invitation is to move from watching the experiment to testing decisions against your own business context. Explore the Firmulate pilot or contact contact@firmulate.com.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.